October 29, 2025
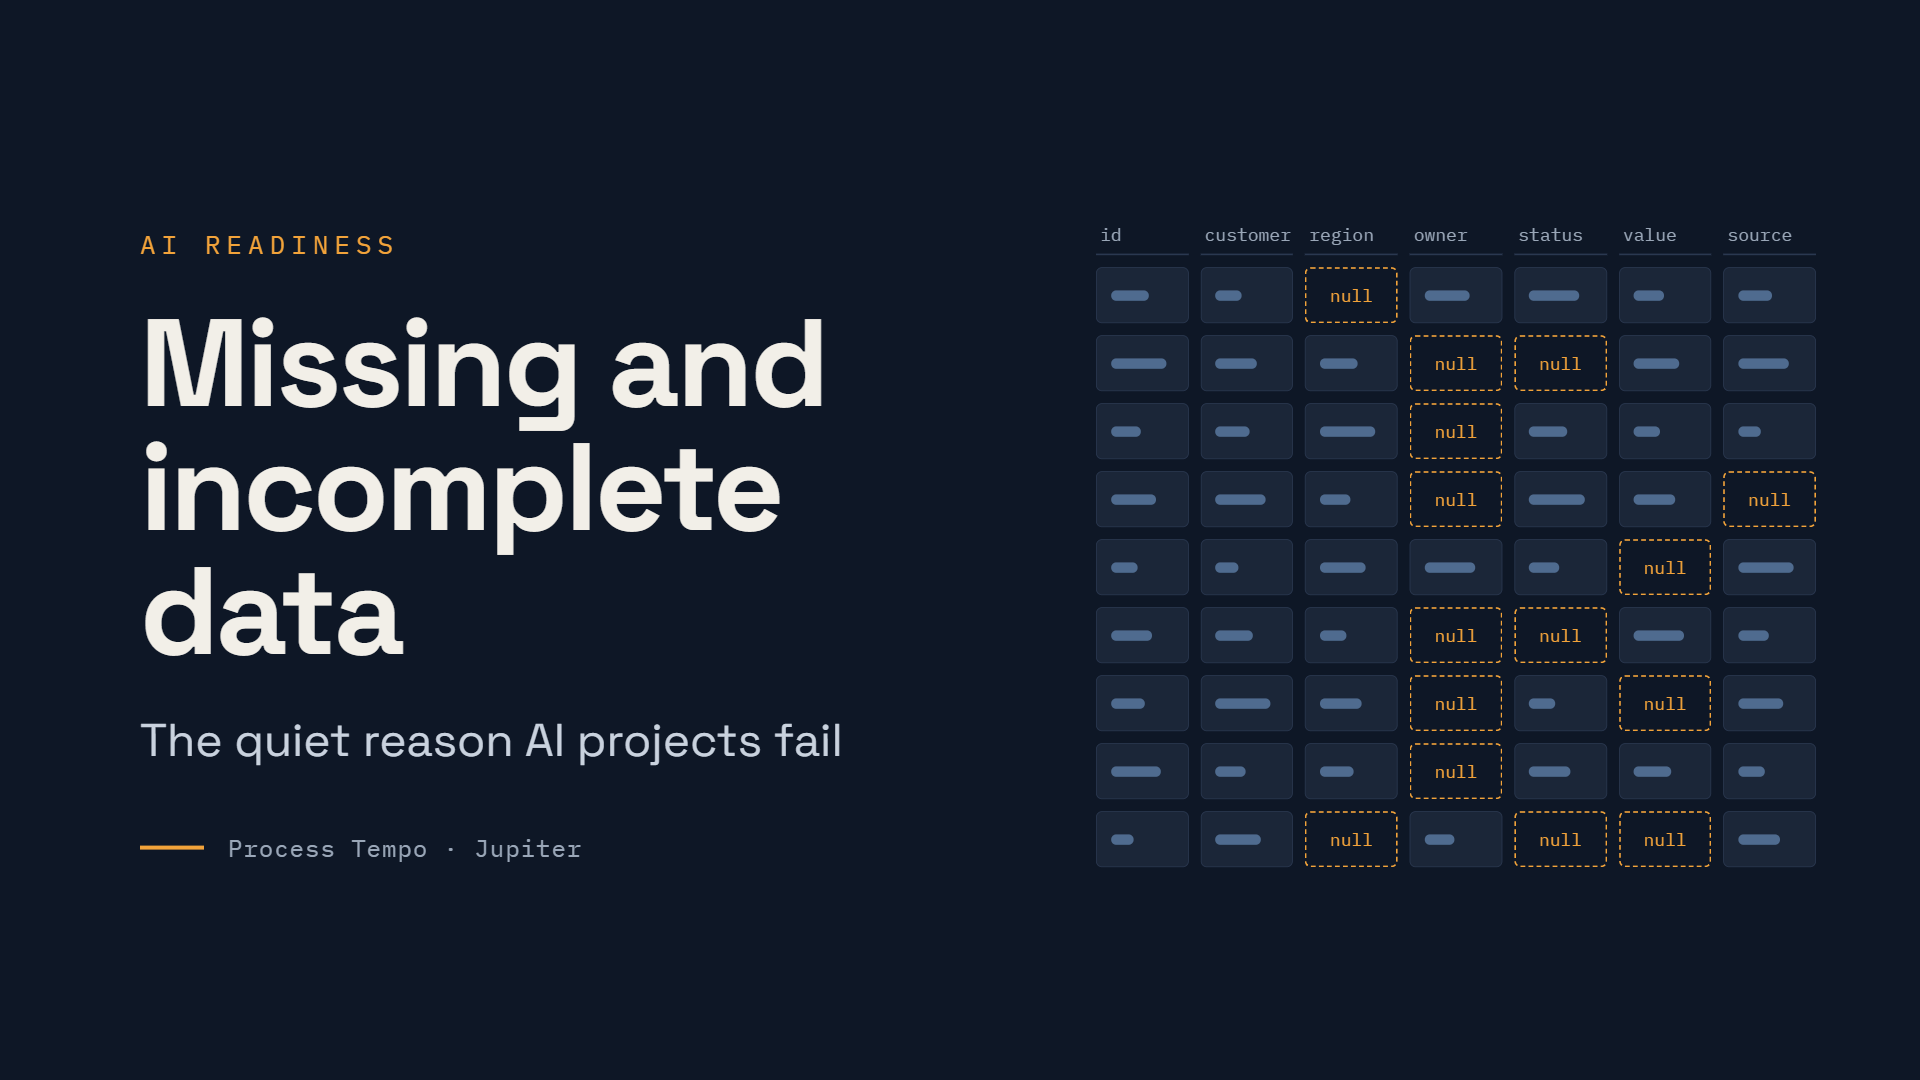
Ask AI consultants why projects stall, and you'll hear the same four words again and again: "missing or incomplete data."
It's rarely the model. It's rarely the vendor. More often, the organization simply doesn't have the data its AI needs, or has it scattered across systems nobody fully understands. The good news is that this is a solvable problem. The bad news is that most organizations try to solve it in the wrong place.
The consultants aren't exaggerating. Research firms, academics, and data leaders keep arriving at the same conclusion.
Gartner puts a number on it. In February 2025, analyst Roxane Edjlali published a prediction that through 2026, organizations will abandon 60% of AI projects that aren't supported by AI-ready data. Gartner's position is blunt: "If the data has issues, the data is not ready for AI." Its supporting survey found that 63% of organizations lack confidence in their data management practices for AI. (Gartner)
RAND Corporation went straight to practitioners. Its 2024 study interviewed 65 experienced data scientists and engineers and found that many AI projects fail because the organization lacks the data needed to train an effective model. One interviewee summed it up: "80 percent of AI is the dirty work of data engineering." (RAND)
Andrew Ng, founder of Google Brain and Landing AI, has spent years arguing that AI teams focus too much on models and too little on data. In his view, if most of the work is data preparation, then "ensuring data quality is the important work of a machine learning team." (Dell)
Data leaders agree. In Informatica's survey of 600 chief data officers, 42% named data quality as the top obstacle to generative AI. Paycor's Chris Eldredge put it simply: "AI is only as good as the data that trains it." (Informatica)
Perhaps the most sobering figure comes from Precisely and Drexel University's LeBow College of Business: only 12% of organizations say their data is of sufficient quality and accessibility for AI. (Precisely)
Missing data is usually a symptom, not the disease. In most organizations, the disease is shadow IT.
Every business runs critical processes on spreadsheets, Access databases, and custom apps that someone built years ago to fill a gap. These tools work well enough for the people who use them every day. But they share the same weaknesses:
The problem stays hidden until someone launches an AI project. Then the team goes looking for data, pulls exports from a dozen disconnected sources, and discovers the gaps all at once. Records don't match. Key fields are empty. History is missing. Months that were budgeted for building the model get spent on cleanup instead.
The obvious response is to replace all of it: retire the spreadsheets, consolidate onto a new ERP, and start fresh. In theory, that fixes everything. In practice, it rarely works.
Large system replacements take years and carry their own high failure rates. They also create new data problems, since migrations are one of the most common ways records go missing. And they ignore why shadow IT exists in the first place: the official systems didn't meet a team's needs, so the team built something that did. Replace those tools without solving that need, and new spreadsheets appear within a year.
Meanwhile, the AI roadmap waits. Gartner's advice points in a different direction: align data work to specific AI use cases instead of trying to fix everything at once. That means starting where the value is, one process and one department at a time.
Process Tempo Jupiter is a no-code, low-code application platform built for data professionals. It's designed to replace the spreadsheets and custom apps behind shadow IT with connected, governed applications, without a multi-year replacement program. Here's how it addresses missing and incomplete data at the root.
It fixes data where it's created. Most data quality tools clean up problems after the fact. Jupiter applications enforce validation rules, required fields, and standardized inputs at the moment data is entered, so incomplete records don't get saved in the first place.
It collects missing data through workflows. When information is missing, Jupiter can route a task to the person responsible for providing it. Dashboards highlight the gaps, and workflows close them. Teams can act on a problem the moment they see it, instead of just reporting on it.
It makes ownership visible. When a process moves out of someone's private spreadsheet and into a shared application, everyone can see who owns the data, who changed it, and when. Built-in logging creates an audit trail that supports both governance and trust in AI outputs.
It connects instead of copying. Jupiter works directly with enterprise data platforms such as Databricks, Snowflake, Google BigQuery, and Neo4j, without moving data to a separate system. Data captured in a Jupiter app lands where AI and analytics teams already work. There's no export, no fragile ETL step, and no scramble to compile data from a dozen sources when an AI project begins.
It maps to how your business thinks. The underlying data model can be organized around specific subject areas and domains: customers, suppliers, assets, contracts. Native support for graph databases lets teams capture the relationships between these domains, which is exactly the context modern AI needs.
It grows one department at a time. Because Jupiter apps are built by data teams using skills they already have, organizations can modernize incrementally. Start with the process that feeds your highest-priority AI use case. Prove the value. Then move to the next one.
It stays useful after the AI goes live. Deployed AI still needs people to review, approve, and correct its outputs. Jupiter applications can serve as that interface, and every correction becomes better data for the next version of the model. With Jupiter 6.0's AI agents and its Galileo assistant, the same platform that collects clean data can also put that data to work.
No platform makes data problems disappear overnight. Teams still have to agree on definitions, accept ownership, and bring historical data forward. But those efforts succeed far more often when every new record is captured cleanly, every process is visible, and every application writes directly to the platform your AI depends on.
That's the foundation Jupiter is built to provide. Instead of waiting years for a perfect architecture, organizations can begin replacing the shadow IT that creates missing data today, starting with the processes that matter most.
If missing or incomplete data is holding back your AI initiatives, talk to the Process Tempo team about where to start.
Build enterprise-ready applications without writing code.
